The relentless pursuit of larger neural networks has finally collided with the hard reality of unit economics, forcing a shift from raw computational power to the sophisticated art of intelligent request delegation. This transition is not merely a technical adjustment but a fundamental reconfiguration of how intelligence is consumed across the global economy. By 2026, the industry has realized that sending a simple weather query to a trillion-parameter model is as fiscally irresponsible as hiring a nuclear physicist to solve a basic arithmetic problem. Model routing has emerged as the essential connective tissue of this new era, serving as a dynamic traffic controller that balances the precision of frontier systems with the speed and affordability of lightweight alternatives.
As organizations scale their AI deployments, the friction between high-performance expectations and sustainable operational costs has become a primary bottleneck. This architectural layer effectively navigates that tension by functioning as an automated intermediary that evaluates the intent and complexity of every incoming prompt. This methodology marks a decisive departure from the “one-size-fits-all” approach that dominated the early part of the decade, moving instead toward a tiered, multi-model infrastructure. By matching each specific query to the most efficient level of computational power, businesses can optimize for latency and accuracy without sacrificing their bottom line.
The Architecture: How Intelligent Decision-Making Functions
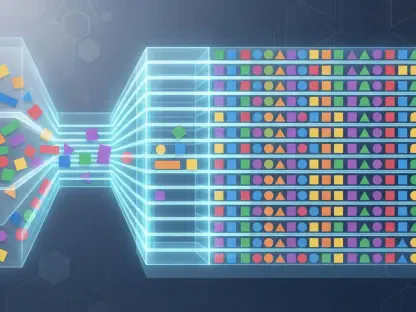
Model routing serves as a strategic gatekeeper, ensuring that the heavy machinery of frontier Large Language Models (LLMs) is reserved exclusively for tasks that demand high-order reasoning. At its core, the system acts as a sophisticated classifier that categorizes tasks based on their linguistic and logical requirements. This ensures that a tiered ecosystem of models—ranging from small, specialized edge models to massive reasoning engines—operates in concert rather than in isolation. The result is a seamless user experience where the complexity of the underlying infrastructure remains hidden behind a single, unified interface.
This dynamic approach effectively manages the high inference costs that have traditionally hindered the mass adoption of top-tier AI services. By diverting high-volume, low-complexity requests to smaller models, organizations can maintain a consistent quality of service while significantly reducing their total cost of ownership. This architectural shift acknowledges that not all tokens are created equal and that the true value of AI lies in the precision of its application rather than the sheer size of its parameter count. Consequently, routing has become the standard for any enterprise seeking to deploy AI at a meaningful scale.
Core Mechanisms: Approaches to Routing Methodologies
Logic-Based Analysis: Evaluation through Metadata
Modern routing systems rely on real-time linguistic analysis to determine the reasoning depth required for a specific prompt. These implementations often utilize a lightweight, specifically trained language model to act as a “pre-classifier,” assessing task types such as creative writing, coding, or data extraction. This “Smart Routing” prevents the over-allocation of resources by automatically selecting the most cost-effective model capable of fulfilling the request. Developers are no longer required to manually specify models, as the system dynamically adjusts based on the live context of the interaction.
Furthermore, this analysis is performed with a strict focus on privacy and efficiency, as modern routers process metadata without the need to store sensitive user information. This allows for a high degree of adaptability, where the routing logic can be updated independently of the core models. By isolating the decision-making process from the task execution, providers can swap out underlying models as newer or cheaper versions become available. This flexibility ensures that the routing layer remains a future-proof component of the technology stack, capable of evolving alongside the rapidly changing AI landscape.
Contextual Awareness: The Role of Session Affinity
Advanced routing proxies have evolved to evaluate entire interaction sessions rather than viewing prompts as isolated events. By calculating derived metadata throughout a conversation, these systems can predict the expected downstream workload and the current state of the system’s cache. This prevents the unnecessary expenditure of “reasoning effort” on repetitive or simple follow-up questions that do not require the depth of a frontier model. Maintaining this contextual awareness is vital for providing a cohesive experience, as it ensures the model “remembers” the tone and constraints of the previous turn.
Beyond simple memory, session affinity mechanisms allow for a consistent dialogue by pinning a user to a specific model when consistency is paramount. However, the router remains vigilant, ready to escalate the session to a more capable model if the complexity of the conversation shifts suddenly. This fluid transition between model tiers happens without the user ever detecting a change in the underlying engine. Such sophistication ensures that high-fidelity models are only engaged when they are truly necessary to sustain the quality of the interaction.
Tiered Escalation: Dynamics of Algorithmic Selection
Sophisticated frameworks now employ “escalation routers” designed to purposefully initiate interactions with the most efficient resources available. If the initial model fails to meet a certain confidence threshold or if the system detects that the user is struggling to get a correct answer, the session is migrated to a frontier model. This tiered approach is based on the observation that the vast majority of daily tasks can be handled by mid-sized models, leaving the most expensive resources to handle the remaining 20% of high-logic requests. This algorithmic selection process acts as a safety net that captures complexity without overspending on simplicity.
These escalation policies are often guided by “LLM-as-a-judge” classifiers, which audit the outputs of smaller models in real-time. If the judge determines that a response is likely to be hallucinated or insufficient, it triggers a re-route to a stronger reasoning engine. This layer of verification adds a critical level of reliability to AI systems, making them suitable for high-stakes enterprise environments. By prioritizing both speed and accuracy through an tiered structure, organizations can achieve a balance that was previously thought impossible with a single-model setup.
Emerging Trends: Navigating Industrial Shifts
The landscape of model routing is rapidly moving toward native integration within cloud gateways and Integrated Development Environments (IDEs). We are seeing a clear industry shift toward “autonomous step-execution” in agentic workflows, where a single complex request is broken down into sub-tasks. Each of these sub-tasks is then routed to a different model optimized for that specific function—such as one for searching the web and another for synthesizing the findings. This modularity allows for a much higher “quality-per-dollar” ratio and significantly improves latency by parallelizing work across specialized engines.
Moreover, the focus has expanded beyond simple cost savings to include operational resilience and the avoidance of vendor lock-in. By building a routing layer that is model-agnostic, organizations can shift their workloads between OpenAI, Anthropic, or open-source models based on current availability and performance. This flexibility is becoming a critical component of corporate strategy in 2026, as it mitigates the risk associated with depending on a single AI provider. As the market matures, the ability to orchestrate a diverse fleet of models is proving to be more valuable than the capabilities of any individual model.
Real-World Applications: Strategies for Deployment
Enterprise Scale: Optimization in Agentic Workflows
In large-scale corporate environments, model routing handles millions of daily interactions with high precision. For instance, in automated technical support, a router ensures that basic account inquiries are handled by ultra-fast, low-cost models, while intricate troubleshooting is escalated to a frontier system. This hierarchical deployment is particularly visible in platforms like Snowflake’s Cortex AI, where routing acts as a central nervous system for complex business processes. Such systems ensure that the right amount of intelligence is applied to every step of a transaction, maximizing both throughput and accuracy.
The implementation of routing in coding assistants has also revolutionized software development by allowing for real-time code completion on local models while delegating complex architectural refactoring to the cloud. This hybrid approach reduces the latency of the developer’s experience while maintaining the high-level reasoning required for structural changes. By distributing the workload based on the specific requirements of the task, enterprises have managed to scale their AI capabilities without an exponential increase in their cloud budgets.
Community Implementations: Learning from Human Preference
Outside of the corporate sphere, community-driven platforms like OpenRouter are shaping the technology by routing requests based on aggregate usage patterns and human preference data. These platforms leverage the collective experience of thousands of users to identify which models perform best for specific creative or technical tasks. This collaborative filtering approach provides a real-world benchmark that often moves faster than formal academic testing. It allows smaller developers to access the same level of routing sophistication that was once reserved for the largest technology companies.
Academic frameworks are also contributing to this evolution by exploring “RouteLLM” models that are specifically trained to predict the “difficulty” of a prompt. These routers use data augmentation and preference learning to refine their decision-making processes, often achieving high accuracy with very low overhead. By treating routing as a machine learning problem in its own right, researchers are creating systems that can self-optimize over time. This continuous improvement ensures that the routing layer becomes smarter as it processes more data, further narrowing the gap between performance and cost.
Technical Hurdles: Avoiding the Pareto Trap
Infrastructure Overhead: The Burden of Quality Auditing
While the benefits of routing are significant, the technology introduces a new set of logistical challenges that organizations must manage carefully. Maintaining a robust routing infrastructure requires constant monitoring to ensure that the “traffic controller” itself does not become a point of failure or a source of latency. Furthermore, the cost of ongoing quality auditing is non-trivial, as human reviewers must periodically verify that the router is making the correct choices. Without this oversight, the system risks degrading the user experience by consistently under-powering the models assigned to complex tasks.
Organizations also face the challenge of keeping their routing logic up to date as the underlying models are updated or replaced. A routing strategy that worked perfectly for one version of a model may lead to inefficiencies or errors in the next. This creates a need for continuous integration and testing cycles specifically for the routing layer. While the token savings are often massive, the engineering hours required to maintain a high-fidelity routing system represent a significant investment that must be weighed against the direct financial gains.
Strategic Risks: The Danger of Hidden Failures
The most pervasive risk in this field is the “Pareto trap,” a situation where a system is so well-optimized for the common 80% of tasks that it fails to recognize the subtle complexities in the remaining 20%. These “middle ground” tasks often look simple on the surface but require deep reasoning to avoid plausible but incorrect answers. If a router misclassifies these tasks and sends them to a low-cost model, the resulting “hidden failure” can be far more damaging than a total system outage. Such errors erode user trust and can lead to costly real-world consequences in sectors like finance or healthcare.
To mitigate this risk, sophisticated deployments are moving toward more conservative routing thresholds and holistic monitoring. Instead of just tracking token costs, teams are beginning to monitor downstream business metrics, such as support ticket volume or user retention, to detect when a router is under-performing. High-fidelity routing models that use more than just keyword matching are becoming essential for distinguishing between truly easy tasks and those that are deceptively complex. The goal is to build a system that is biased toward quality, only defaulting to cheaper models when the probability of a correct outcome is near-certain.
Future Outlook: Identifying Breakthrough Potential
The trajectory of AI model routing points toward a future where predictive sophistication is deeply embedded in every layer of the technology stack. We can expect the emergence of routers that do not just choose between models, but actually “distill” requests into specialized sub-queries tailored for specific architectures. As the industry moves toward agentic and autonomous systems, the routing layer will evolve into a sophisticated orchestrator capable of managing thousands of specialized micro-models simultaneously. This will enable a level of resource management that makes high-end AI capabilities accessible to organizations of all sizes.
Long-term, the integration of routing with hardware-level optimizations could allow for even more dramatic efficiency gains. Future systems might route tasks between local on-device processors and global cloud clusters based on real-time energy prices or network latency. This holistic approach to resource allocation will be the key to making AI a truly ubiquitous utility. By treating intelligence as a flexible resource that can be scaled up or down instantly, model routing has laid the groundwork for the next generation of decentralized and sustainable artificial intelligence.
Final Assessment: Review of Routing Technology
The transition toward model routing represented a departure from the era of brute-force scaling and introduced a more mature, architectural approach to artificial intelligence. This technology performed as expected by providing a critical buffer between the escalating costs of frontier models and the practical needs of enterprise-scale deployment. The industry moved away from the unsustainable “one-size-fits-all” model, and developers began to implement routing as a standard layer for operational resilience. While the Pareto trap emerged as a significant strategic hurdle, the organizations that adopted conservative, quality-biased routing strategies found the benefits to be undeniable, often achieving cost reductions between 50% and 95%.
Next steps for the industry involved moving beyond simple classification toward more predictive, high-fidelity orchestration. Routing provided a multi-dimensional tool for cost management and performance optimization that shifted the burden of decision-making from the developer to the infrastructure itself. Ultimately, the success of AI deployments in the mid-2020s depended not on the raw power of a single model, but on the robustness of the system that governed its use. The verdict was clear: a well-implemented routing system became the defining factor in whether an AI project was a laboratory experiment or a viable, scalable business solution.