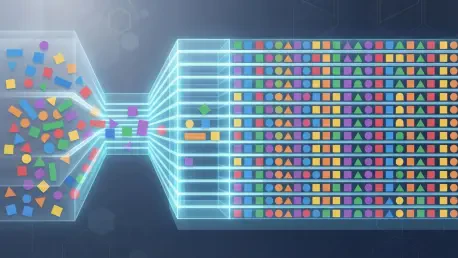
Advanced Kubernetes primitives like PriorityClasses and Preemption ensure that critical pre-merge checks can displace lower-priority nightly regression suites during peak demand. This capability has become a cornerstone for modern engineering organizations that manage thousands of repositories and require a unified, authoritative validation plane. In the current landscape of 2026, the transition from decentralized testing frameworks to centralized infrastructure orchestration is no longer just a trend but a necessity for maintaining high-velocity delivery. Large-scale enterprises, particularly those operating in high-volume financial services, face the daunting task of executing upwards of 250,000 automated tests per day. Managing this volume through fragmented, team-specific runners leads to significant resource waste and inconsistent quality signals. By adopting a centralized model built on Amazon Elastic Kubernetes Service (EKS), these organizations can transform their testing pipelines into a multi-tenant, quota-aware system that serves as the definitive certification engine for every software release across the entire enterprise ecosystem.
The shift toward centralized orchestration represents a fundamental change in the software development lifecycle, moving the focus from how tests are written to how they are reliably executed at scale. As organizations scale, the bottleneck for delivery frequently shifts from code production to code validation. Without a robust infrastructure to handle the bursty nature of developer workflows, the system becomes prone to gridlock, where release cycles are delayed by the lack of available compute resources. A centralized execution plane provides a standard interface for all engineering teams, abstracting the underlying complexity of the cloud environment while providing the platform team with the levers necessary to ensure stability and performance. This move toward infrastructure-as-a-product allows organizations to implement rigorous admission controls and global scheduling policies that align resource consumption with the overarching business priorities, ensuring that the most critical code changes are validated with the highest possible priority and minimal latency.
Strategic Productization: Managing Testing as a Service
Centralizing test execution only provides a tangible return on investment when the underlying infrastructure is managed with a product-centric mindset rather than as a simple utility. In a shared Kubernetes environment, the absence of strict admission controls and defined priority tiers inevitably leads to a noisy neighbor scenario. This occurs when a single team with massive or inefficient test suites consumes a disproportionate amount of the available cluster capacity, thereby increasing wait times for all other teams and stalling the entire organization’s productivity. To mitigate this risk, platform engineers must treat the testing environment as a high-availability product that requires governed access and transparent resource distribution. By implementing admission controllers and fair-share scheduling, the platform ensures that the cluster remains healthy and that resources are allocated based on strategic business urgency rather than a simple first-come, first-served queue, which is essential for maintaining a balanced and equitable developer ecosystem.
The success of a productized testing platform is measured by its ability to maintain strict service-level objectives for developer feedback loops while maximizing hardware utilization. In 2026, the focus has moved toward creating a “certification” model where a software version is only deemed ready for deployment once it has passed its required validation suites on the authoritative, shared infrastructure. This model eliminates the “it works on my machine” problem and provides a single source of truth for software quality across the company. To achieve this, the platform must offer a seamless user experience that abstracts the intricacies of Kubernetes from the developers, allowing them to focus on writing high-quality tests while the infrastructure handles the complexities of scaling, sharding, and fault tolerance. Treating testing as a product also involves continuous improvement based on usage data, identifying bottlenecks in execution times, and providing teams with the insights they need to optimize their suites for better performance within the shared environment.
Architectural Design: The Three-Plane Operational Model
A scalable and resilient testing platform is built upon a logical three-plane architecture consisting of the Control Plane, the Execution Plane, and the Results Plane. The Control Plane serves as the primary entry point for all test requests, providing a stable API that abstracts the underlying Kubernetes complexity from the end users. This abstraction is vital because it allows the platform engineering team to perform critical maintenance, such as upgrading cluster versions or modifying scheduling logic, without requiring any changes from the thousands of development teams that rely on the system. Within this layer, specialized components like Kueue manage the admission and queuing of jobs, ensuring that workloads are only admitted to the cluster when the necessary quotas are available. This prevents resource exhaustion and allows for a more predictable execution environment where high-priority tasks are gated correctly and low-priority background tasks are deferred during periods of peak cluster utilization.
The Execution Plane is where the actual computational work occurs, utilizing Kubernetes Indexed Jobs to handle the sharding of large-scale test suites. Sharding is the process of decomposing a massive test suite into smaller, parallelizable units, and by using the indexed completion mode, each pod in a job receives a unique index that determines which specific subset of tests it should execute. To handle the extreme volatility of developer demand, which often spikes before release cutoffs, the Execution Plane leverages dynamic node provisioners like Karpenter. This technology evaluates the specific resource requirements of pending pods in real-time and provisions the most cost-effective hardware, including spot instances or specialized compute nodes, to meet the demand. Meanwhile, the Results Plane transforms raw execution logs and success metrics into actionable certification records. In highly regulated sectors, this layer is responsible for creating immutable evidence that a specific software version has met all required quality gates, ensuring that the reporting process is as reliable and reproducible as the execution itself.
Efficiency Primitives: Maximizing Kubernetes Native Capabilities
The operational stability of a multi-tenant testing environment is heavily dependent on the clever application of advanced Kubernetes primitives that manage resource allocation and workload urgency. Beyond the use of PriorityClasses and preemption to handle mixed-urgency tasks, the platform must enforce strict ResourceQuotas and LimitRanges to maintain cluster health. These primitives prevent a single poorly written or unbounded test from consuming excessive memory and potentially causing node instability or impacting neighboring test pods. While memory is strictly capped to prevent Out-Of-Memory events, the platform often allows CPU usage to burst above the requested levels. This approach provides the necessary processing power to accelerate test execution during intensive cycles without requiring the organization to over-provision the entire cluster, leading to a significant reduction in overall cloud expenditure and improved execution speed for the developers.
Another critical advancement in the Kubernetes ecosystem that enhances testing efficiency is the implementation of the BackoffLimitPerIndex feature within the Job API. Historically, if a single shard in a massive 100-pod test job failed due to a transient infrastructure issue, the entire job might have needed a complete restart, leading to massive delays and wasted compute resources. With the current per-index backoff capabilities, the platform can automatically retry only the specific shards that failed, leaving the successful portions of the suite untouched. This granular control over retries significantly improves the overall reliability of the testing pipeline and ensures that transient network glitches or node interruptions do not derail an entire release cycle. By leveraging these native Kubernetes features, platform engineers can build a system that is both highly resilient to environmental failures and extremely cost-effective, providing a robust foundation for the massive-scale validation required by modern enterprise software development.
Reliability Engineering: Combatting Systemic Test Flakiness
In an environment where 250,000 tests are executed daily, even a minor flakiness rate of 1.5% can result in thousands of misleading failure signals that erode developer trust and stall delivery. Test flakiness, where a suite produces inconsistent results for the same code, must be addressed as a systemic infrastructure concern rather than a simple code quality issue. The architecture handles this by incorporating automated retry mechanisms that execute failed shards on entirely fresh pods to determine if the failure was caused by a transient environmental factor. If a test passes on the second attempt, it is automatically flagged as a flake and categorized accordingly. This visibility allows the platform team to distinguish between genuine assertion failures in the code and platform-induced errors, such as network timeouts or resource contention, which is essential for maintaining the credibility of the entire automated validation system across the organization.
To further manage the impact of unreliable tests, the platform implements sophisticated quarantine and classification workflows. Tests that are identified as consistently flaky are moved into a quarantine state, where they continue to run to provide data but do not block the formal release certification process. This policy ensures that a single unstable test does not prevent an entire team from deploying critical updates, while simultaneously providing the owning team with a clear mandate to resolve the underlying race conditions or dependency issues. Furthermore, the platform utilizes its deep visibility into the Kubernetes cluster state to analyze failures in context, identifying if a test pod was terminated due to a node eviction or an infrastructure-level event. By automating the triage of these failures and providing developers with a clear taxonomy of why a test failed, the organization can maintain a high-velocity release cadence while aggressively pursuing the root causes of instability within their test suites.
Resource Orchestration: Navigating Peak Demand Cycles
The most significant challenge for a centralized testing platform often occurs during the release-morning crunch, when multiple teams across the organization attempt to run their final regression suites simultaneously. In a traditional, unmanaged system, the first team to submit their jobs would likely consume all available resources, leaving others in a state of indefinite waiting. However, by utilizing Kubernetes-based orchestration with fair-sharing and borrowing limits, the system ensures that compute capacity is distributed equitably among all participating cohorts. If one team has idle quota, others can “borrow” that capacity to speed up their own validation, but the system remains capable of reclaiming those resources the moment the original owner needs them. This dynamic reallocation of resources ensures that no single team is unfairly penalized by the activity of others and that the organization as a whole can maximize its total throughput.
This sophisticated scheduling model is further enhanced by the use of preemption to manage emergency situations where a critical fix must be validated immediately. When a high-priority job is submitted to the cluster, the Kubernetes scheduler can displace lower-priority nightly regression tasks or background suites to make room for the urgent workload. This ensures that the organization can always prioritize the most time-sensitive tasks, regardless of how busy the cluster might be at that moment. By maintaining a high level of utilization—often reaching 100% of the available pool during peak windows—the platform proves its value as a highly efficient engine for software delivery. The combination of just-in-time scaling via Karpenter and priority-aware scheduling via Kueue allows the infrastructure to bend and flex in response to the real-time needs of the business, ensuring that the release pipeline remains fluid even under the most demanding operational conditions.
Governance and Security: Protecting the Validation Plane
In the highly regulated world of financial services, security and governance are non-negotiable components of the testing infrastructure. Because test pods essentially run arbitrary code committed by a wide variety of developers, the platform must enforce strict isolation between different tenants to prevent data leakage or unauthorized access. This is achieved through the rigorous use of Kubernetes namespaces, which provide logical boundaries between different teams or repositories. By ensuring that a service account associated with a payments repository cannot access the secrets or results of a trading application, the platform maintains a high degree of security. Furthermore, the environment enforces restricted pod security standards, which prevent test containers from running as root or accessing the underlying host’s file system, thereby mitigating the risk of a compromised test pod affecting the stability or security of the entire cluster.
Identity management and access control are also modernized within this architecture through the use of temporary, least-privilege credentials. Rather than using long-lived API keys, which are prone to theft and misuse, the platform leverages EKS Pod Identity or IAM Roles for Service Accounts (IRSA). This allows individual test pods to securely interact with other cloud resources, such as databases, object storage, or external APIs, using credentials that are automatically rotated and strictly scoped to the specific requirements of that test suite. This level of granular control ensures that even if a test pod is compromised, the potential blast radius is extremely limited. By weaving security into the fabric of the execution plane, organizations can confidently scale their testing efforts while meeting the stringent compliance requirements of the industry, proving that high-speed delivery and robust security are not mutually exclusive goals in a modern cloud-native environment.
Operational Realities: Balancing Centralization with Flexibility
While the benefits of a centralized Kubernetes-based testing platform are extensive, it is important to acknowledge the strategic trade-offs and operational complexities that come with such a system. One of the primary concerns is the creation of a single point of failure; if the orchestration platform experiences an outage, the software delivery capability for the entire organization is effectively paralyzed. This risk necessitates a highly resilient architecture across multiple availability zones and even multiple clusters to ensure continuous operation. Additionally, the platform team can sometimes become a bottleneck for innovation if they are unable to quickly support new hardware requirements, such as specialized GPU instances for machine learning validation. To mitigate this, the platform must be designed with extensibility in mind, allowing for the rapid onboarding of new node types and execution environments as the needs of the engineering teams evolve.
Another operational challenge lies in the management of the “masking risk” associated with automated retries. While retries are essential for maintaining productivity in the face of flakiness, they can occasionally hide genuine, intermittent bugs in the production code that only appear under specific race conditions. To address this, the platform must maintain rigorous logging and visibility into how often retries are being used and for which tests. This data allows the organization to conduct periodic reviews of their test suites and identify areas where the code itself may need to be strengthened to eliminate non-deterministic behavior. Managing the sheer complexity of four or more large EKS clusters also requires a dedicated and highly skilled platform engineering team capable of navigating the intricacies of networking, routing, and cloud-native security. Despite these challenges, the centralized model remains the most effective way to scale validation for a modern enterprise, provided the organization is willing to invest in the necessary operational excellence.
Strategic Evolution: Establishing the Certification Culture
The successful implementation of this massive-scale orchestration platform fundamentally changed how quality was perceived within the organization. By shifting from a decentralized framework model to a centralized infrastructure product, the engineering teams established a consistent and trustworthy foundation for all software releases. This transition allowed the business to leverage change-based test selection and advanced observability tools, which focused resources only on the tests most likely to be impacted by a code change. The platform leveraged OpenTelemetry to provide a comprehensive trace of every test run, from the initial submission to the final certification, allowing engineers to identify and resolve performance bottlenecks with unprecedented precision. This data-driven approach moved the organization away from the traditional “all-or-nothing” regression model toward a more intelligent and efficient validation strategy that optimized for both speed and accuracy.
In the final assessment, the move to Kubernetes-based orchestration provided a competitive advantage that enabled the rapid deployment of high-quality financial software. The platform was designed to not only run tests but to serve as the definitive authority on release readiness, creating a transparent and immutable record of quality for every commit. This established a culture where developers felt empowered by the infrastructure rather than restricted by it, as the system provided clear failure taxonomies and actionable insights that reduced the time spent on manual triage. As the organization looked toward further optimizations, such as AI-assisted failure analysis and even deeper integration with cloud-native development environments, the foundation created by this orchestration model remained the vital core of their delivery pipeline. The journey toward scaling 250,000 tests a day proved that when testing was treated as a first-class engineering product, it ceased to be a cost center and became a driver of organizational agility.